
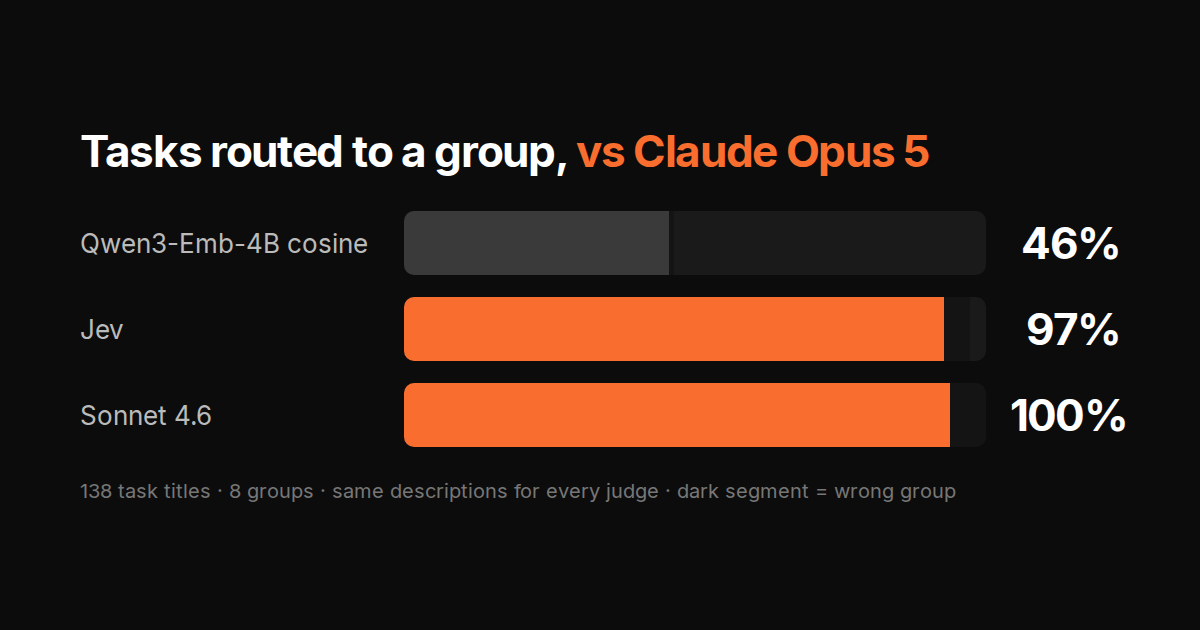
Cosine similarity between a task title and a group description is not a classifier.
Bench, cases, raw verdicts: backend/bench/categorization in the TODOforAI repo. Total
cost ~$0.50.
Setup
TODOforAI boards have groups (SEO, Paid, Frontend…); new tasks get a suggested
group. V1: embed title and group name + description, nearest cosine wins. Embedder
Qwen/Qwen3-Embedding-4B via DeepInfra, 512 dims, unit-normalized, query instruction
“Given a task, retrieve the workstream whose purpose best matches the task”. Abstain if
best < 0.50 or margin to runner-up < 0.06.
100% precision on 18 hand cases. Most of my real board in Unsorted.
Judges
Same 138 titles, same 8 groups, same description text, no example tasks — exactly what
production sees. Titles written like real todos: short, half Hungarian, 15 nonsense
(call mom, asdf), 5 ambiguous.
- embedding — production, unchanged
- jev — TypeSafe Jev, non-autoregressive
decision model on Vercel AI Gateway. One
choicequestion, 8 groups +none. $0.04/MTok in, output free. - sonnet — Claude Sonnet 4.6, temp 0, one slug or
none - opus — Claude Opus 5, same prompt. The truth. My labels are one more opinion.
Trap: Opus 5 reasons before answering; max_tokens: 20 looked like abstaining on 88/138.
Give it 400.
Numbers
| Judge | agrees with Opus | wrong group | missed | 138 tasks |
|---|---|---|---|---|
| embedding | 77/138 | 1 | 60/112 | 8 s |
| jev | 130/138 | 5 | 3/112 | 24 s |
| sonnet 4.6 | 131/138 | 7 | 0/112 | 57 s |
Opus routed 112, called none on 26 (15 nonsense + 11 vague). Embedding: wrong once,
missed 54%. Jev: 97% routed, 5 wrong. Sonnet’s 7 wrong are coin flips with Opus.
On my real board Jev and Opus agree 21/26.
Why the embedding abstains
Not the margin:
                         agree   wrong   missed
margin 0.06  floor 0.50    76      2       60     ← production
margin 0     floor 0.50    79     41       18
margin 0     floor 0       76     62        0
Drop the gate and Unsorted becomes wrong group. Top-1 is wrong on ~45% of tasks.
bun test flaky on CI          frontend 0.540   development 0.537
call mom                      email 0.540      plg 0.525
asdf                          development 0.663  frontend 0.659
Scores sit in 0.42–0.72; asdf outscores a real task, so no floor finds nonsense.
Frontend/Development, Paid/SEO, Enterprise/Paid overlap, so real tasks sit inside any
margin. Jev and the LLMs know outcomes: a CI flake is Development because of what fixing
it achieves. Similarity can’t say that.
What shipped
Jev routes; embedding is fallback when the gateway is unset or down. Batches of 25,
none explicit, accept probability ≥ 0.5. ~0.3 s per task.
Not Sonnet: 57 s vs 24 s and ~100× the price, for a suggestion 400 ms after you stop typing.
| Router | per 1,000 tasks | per 1M tasks |
|---|---|---|
| embedding (~15 tok, $0.01/MTok) | $0.0002 | $0.15 |
| jev (~260 tok catalog per question, $0.04/MTok in, out free) | $0.01 | $10 |
| sonnet 4.6 (~350 in / 10 out) | $1.20 | $1,200 |
| opus 5 (~350 in / ~200 out with reasoning) | $7 | $7,000 |
List prices, 8 groups. Jev costs ~70× the embedding and routes twice as much.
Jev’s 5 wrong are channel-vs-outcome (sponsor a newsletter, measure signups → email,
not paid). Confidence is lower when wrong (0.70 vs 0.94), but floor 0.6 trades 2 wrong
for 7 Unsorted. We keep the 5.
Takeaways
- Precision alone lies. Print recall against something you trust.
- Score against a strong model, not your own labels.
- Check the reference’s output budget. Truncated looks cautious.
138 cases is small. It’s enough to see a 54% recall gap; that’s the only claim.